
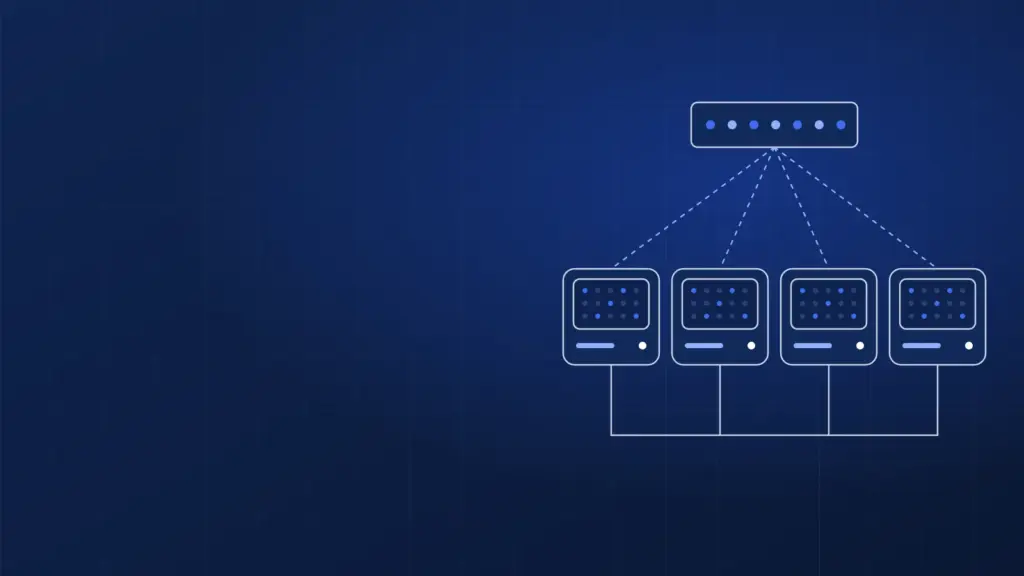
A single DGX Spark has 128 GB of memory and runs models of up to about 200 billion parameters. A DGX Spark cluster of two units linked by a 200 Gb/s QSFP cable gives you 256 GB and models up to ~400B; four units behind a 200 GbE switch give you 512 GB and models up to ~700B. Here is how it works, which models genuinely fit, and where the approach stops making sense.
Most coverage of DGX Spark clustering focuses on “700 billion parameters on your desk”. The number is impressive, but it rests on specific assumptions: 4-bit quantisation, a limited context window, and the understanding that a cluster mainly adds memory capacity, not speed. We build and operate these clusters in our Tier III data center in Poland, so this article looks at them from an engineering angle, with the memory maths worked out for current open-weight models.
Why cluster DGX Spark at all
A single DGX Spark is a GB10 Grace Blackwell Superchip with 128 GB of LPDDR5X memory shared by CPU and GPU. According to NVIDIA that is enough for inference on models up to 200B parameters and fine-tuning up to 70B. Many of the most interesting open models of 2026 are bigger, though: Llama 4 Maverick has around 400B parameters, GLM-5.3 around 753B and DeepSeek-V4.1-Flash around 763B. None of them fits into 128 GB, even at 4-bit.
A cluster solves the capacity problem. The model is split into parts, each part sits in the memory of a different unit, and the units exchange data over the network. That lets a team work with a 400B–700B class model without renting an eight-GPU HBM server, which costs considerably more and often sits idle during the experimentation phase.
Two ways to cluster DGX Spark
NVIDIA supports two configurations. Every unit has a ConnectX-7 adapter with two 200 Gb/s QSFP ports, intended precisely for linking units together.
| Configuration | Interconnect | Total memory | Models (per NVIDIA) | Typical use |
|---|---|---|---|---|
| 1 unit | – | 128 GB | up to 200B (inference), up to 70B (fine-tuning) | prototyping, fine-tuning, small team |
| 2-unit cluster | direct 200 Gb/s QSFP cable | 256 GB | up to ~400B | 200B–400B models at 4-bit, 120B–180B models at FP8 |
| 4-unit cluster | 200 GbE switch | 512 GB | up to ~700B | large MoE models at 4-bit, ~300B–400B models at FP8 |
Two units: 256 GB, no switch
The simplest option. Two DGX Spark units are connected directly with a QSFP cable, with no extra network hardware. A point-to-point link has the lowest latency, which matters when every layer of the model is split across units (more on that below). This configuration suits a team working with 200B–400B models, or one that wants to run mid-size models at higher precision than 4-bit.
Four units: 512 GB behind a 200 GbE switch
With four units, cabling every unit to every other one stops being practical, so you need a 200 GbE switch. That adds one more network component to configure and monitor, but in return you get 512 GB of memory: enough for ~700B models at 4-bit. In our data center the switch, cabling and network configuration are part of the service.
Which models fit in a DGX Spark cluster: the memory maths
The calculation is simple: weights equal parameters times bytes per parameter. That is about 0.5 bytes at 4-bit, 1 byte at FP8 and 2 bytes at BF16. On top of that you need 10–20% overhead, memory for the KV cache (which grows with context length and the number of concurrent requests) and whatever the operating system on each unit needs. We cover this in detail in How much VRAM does an LLM need.
One important note on mixture-of-experts (MoE) models: they compute only part of their parameters per token (the “active” ones), but they must hold all of them in memory. For memory sizing, always use the total parameter count.
Below are examples for open-weight models as of November 2026 (the market shifts monthly). The weight columns show weights only, without overhead or KV cache.
| Model | Total parameters | Weights at 4-bit | Weights at FP8 | Where it fits |
|---|---|---|---|---|
| Mistral Medium 3.5 | 128B | ~64 GB | ~128 GB | 4-bit: 1 unit; FP8: 2-unit cluster |
| Qwen3.8-Flash-Next | 180B | ~90 GB | ~180 GB | 4-bit: 1 unit (at the limit), comfortably 2 units; FP8: 2-unit cluster |
| GLM-5.3-Flash | ~321B | ~161 GB | ~321 GB | 4-bit: 2-unit cluster; FP8: 4-unit cluster |
| Llama 4 Maverick | ~400B | ~200 GB | ~400 GB | 4-bit: 2 units (tight, short context), comfortably 4 units; FP8: 4 units, at the limit |
| GLM-5.3 | ~753B | ~377 GB | ~753 GB | 4-bit: 4-unit cluster, at the limit; FP8: no |
| DeepSeek-V4.1-Flash | ~763B | ~382 GB | ~763 GB | 4-bit: 4-unit cluster, at the limit; FP8: no |
| Mistral Large 4 (52B active) | ~1T | ~500 GB | ~1 TB | does not fit – HGX server |
| Kimi K2.7-Code | ~1.03T | ~515 GB | ~1.03 TB | does not fit – HGX server |
| DeepSeek-V4-Pro | ~1.65T | ~825 GB | ~1.65 TB | does not fit – HGX B200 (4-bit) or HGX B300 |
What the table tells you:
- A ~400B model on two units is possible but tight. 200 GB of weights plus 10–20% overhead comes to roughly 220–240 GB out of 256 GB. Little is left for the KV cache, so context length and concurrency will be heavily constrained. On four units the same model has plenty of room.
- GLM-5.3 and DeepSeek-V4.1-Flash sit slightly above NVIDIA’s indicative ~700B ceiling. The 4-bit weights alone (around 380 GB) fit in 512 GB, but once overhead is added there is not much left for context. We treat this as a configuration for evaluation, not for day-to-day work on long documents.
- Models of 1T parameters and up are out of reach. Mistral Large 4, Kimi K2.7-Code, DeepSeek-V4-Pro, and even more so Kimi K3 (~2.78T) or Qwen3.8-2.4T, need servers with HBM memory.
- 4-bit quantisation has a cost. Modern methods usually stay close to the original quality, but always verify on your own tasks. We discuss the trade-offs in cutting AI infrastructure costs with quantization.
Size is not the only criterion. Large models often come with custom licences (GLM-5.3, Llama 4 and Mistral Large 4, for example), so check the commercial terms before you deploy. You will find a model comparison including licences in Best open-source LLMs to self-host in 2026.
How distributed inference works
When a model does not fit into one unit’s memory, the inference server (vLLM, SGLang or TensorRT-LLM, for instance) splits it across several units. There are two basic approaches, and in practice they are often combined.
Tensor parallelism
Each layer of the model is split into pieces: the weight matrices are divided across units and each one computes its share. After every layer the units must exchange partial results. The upside is that all units work at the same time on each token, and each reads only its share of the weights from local memory. The downside is very frequent communication: a synchronisation after every layer, which means tens or even hundreds of exchanges per token. In HGX servers that traffic runs over 1.8 TB/s NVLink. Between DGX Spark units it runs over a 200 Gb/s network, roughly 25 GB/s, with noticeably higher latency. That is why tensor parallelism works best over the direct link between two units.
Pipeline parallelism
The model is split into groups of consecutive layers: the first unit handles layers 1 to N, the second N+1 to 2N, and so on. Only the activations at group boundaries travel between units, which is a small amount of data, so this mode is far less sensitive to the network. The trade-off is that a single request passes through the units one after another: the cluster gains capacity, but an individual response does not get faster. With many concurrent requests the pipeline fills up and hardware utilisation improves.
ConnectX-7 supports RDMA, so traffic between units bypasses the operating system’s TCP/IP stack and latency drops. Even so, choosing the mode and tuning it is a matter of testing with a specific model and workload, not a single universal configuration.
Limitations of clustering
A cluster is a way to run a large model at a reasonable cost, not a replacement for a production server. Know the limits before you decide:
- 273 GB/s of memory bandwidth per unit. Text generation is bound by how fast weights can be read. Large dense models will be slow. MoE models do better because each token reads only the active parameters.
- Network instead of NVLink. 200 Gb/s is fast for a network, but many times slower than GPU-to-GPU links in HGX systems. Part of the compute budget goes to communication.
- Four units are not four times faster. A cluster primarily scales memory capacity. Any speed gain is smaller than the number of units, and in pipeline mode a single request may see none at all.
- No redundancy. The model is spread across all units, so if one fails the whole cluster stops. Four units means four potential points of failure.
- Little room for context with the largest models. When weights take up most of the memory, long contexts and many simultaneous users no longer fit.
- Software maturity. Not every model and toolchain combination is equally well tested in multi-node mode on Arm. Run and measure a model before committing to it.
When to move from a DGX Spark cluster to an HGX server
Clustered DGX Spark works well for R&D, for prototyping on large models and for a small team. Moving to an HGX server makes sense when:
- the model is going into production with many concurrent users and response-time requirements,
- you need a model above ~700B parameters, or a large model at FP8 or BF16 rather than 4-bit,
- you need long contexts (for example, analysis of large document sets) on a large model,
- you are planning full fine-tuning or training, not just inference and LoRA,
- the service needs high availability, which means at least two independent servers.
For comparison: HGX B200 has 8 GPUs with 180 GB of HBM3e each, about 1.44 TB in total, linked by 1.8 TB/s NVLink. HGX B300 has 8 GPUs with 288 GB each, roughly 2.3 TB per system. In a server like that, DeepSeek-V4-Pro at 4-bit (about 825 GB of weights) fits with plenty of room for context. We offer these systems as GPU servers as a service, or as Supermicro hardware you buy and place in our data center under colocation. For the full ladder from DGX Spark to HGX, see DGX Spark vs RTX PRO 6000 vs HGX B200.
DGX Spark cluster as a service
We build and operate the cluster in our ISO 27001-certified Tier III data center. The service covers:
- sizing the configuration (2 or 4 units) to the model, precision and required context length,
- connecting the units (QSFP cable or 200 GbE switch) and configuring the network,
- installing DGX OS and the distributed inference stack, deploying the model and exposing it through an OpenAI-compatible API,
- monitoring every unit and the network between them, and backing up configuration and data,
- access over VPN and SSH, with full root access or with administration handled by us.
If you start with a single unit, you can grow it into a cluster without moving your data. The single-unit service is described in NVIDIA DGX Spark as a Service. Pricing is a custom quote based on the number of units, the contract term and the scope of administration.
FAQ: frequently asked questions
How much memory does a DGX Spark cluster have?
Each unit has 128 GB of unified memory. A two-unit cluster has 256 GB in total, a four-unit cluster 512 GB. The operating system on each unit takes a share, so slightly less is available for the model and context.
Can two DGX Spark units run a 405B model?
Yes, at 4-bit quantisation, but it is tight. A 405B model at 4-bit is about 203 GB of weights, or roughly 220–245 GB with overhead, out of 256 GB available. Context length and concurrency will be heavily limited. For comfortable work with a model that size, a four-unit cluster is the better choice.
Are four DGX Spark units four times faster than one?
No. A cluster mainly increases memory capacity, meaning the size of model you can run. Communication over the 200 Gb/s network takes time, and in pipeline mode a single request passes through the units one after another.
Can I run DeepSeek on a DGX Spark cluster?
DeepSeek-V4.1-Flash (~763B) at 4-bit is about 382 GB of weights, which fits in a four-unit cluster, though with little headroom for context. DeepSeek-V4-Pro (~1.65T) needs an HGX server.
How much does a DGX Spark cluster cost as a service?
Pricing is a custom quote. It depends on the number of units (2 or 4), the contract term and whether we or your team handle administration.
DGX Spark cluster or HGX B200 server?
Choose clustered DGX Spark for R&D, prototyping and a small team working with a 200B–700B model. Choose HGX B200 for production with many users, for models above 700B, for higher precision and for training.
Want to run a 400B–700B model on private hardware in the EU? Tell us about the model and how your team works, and we will size the cluster and prepare a quote. Details are on the DGX Spark as a Service page, and you can reach us through the contact form.